How it works
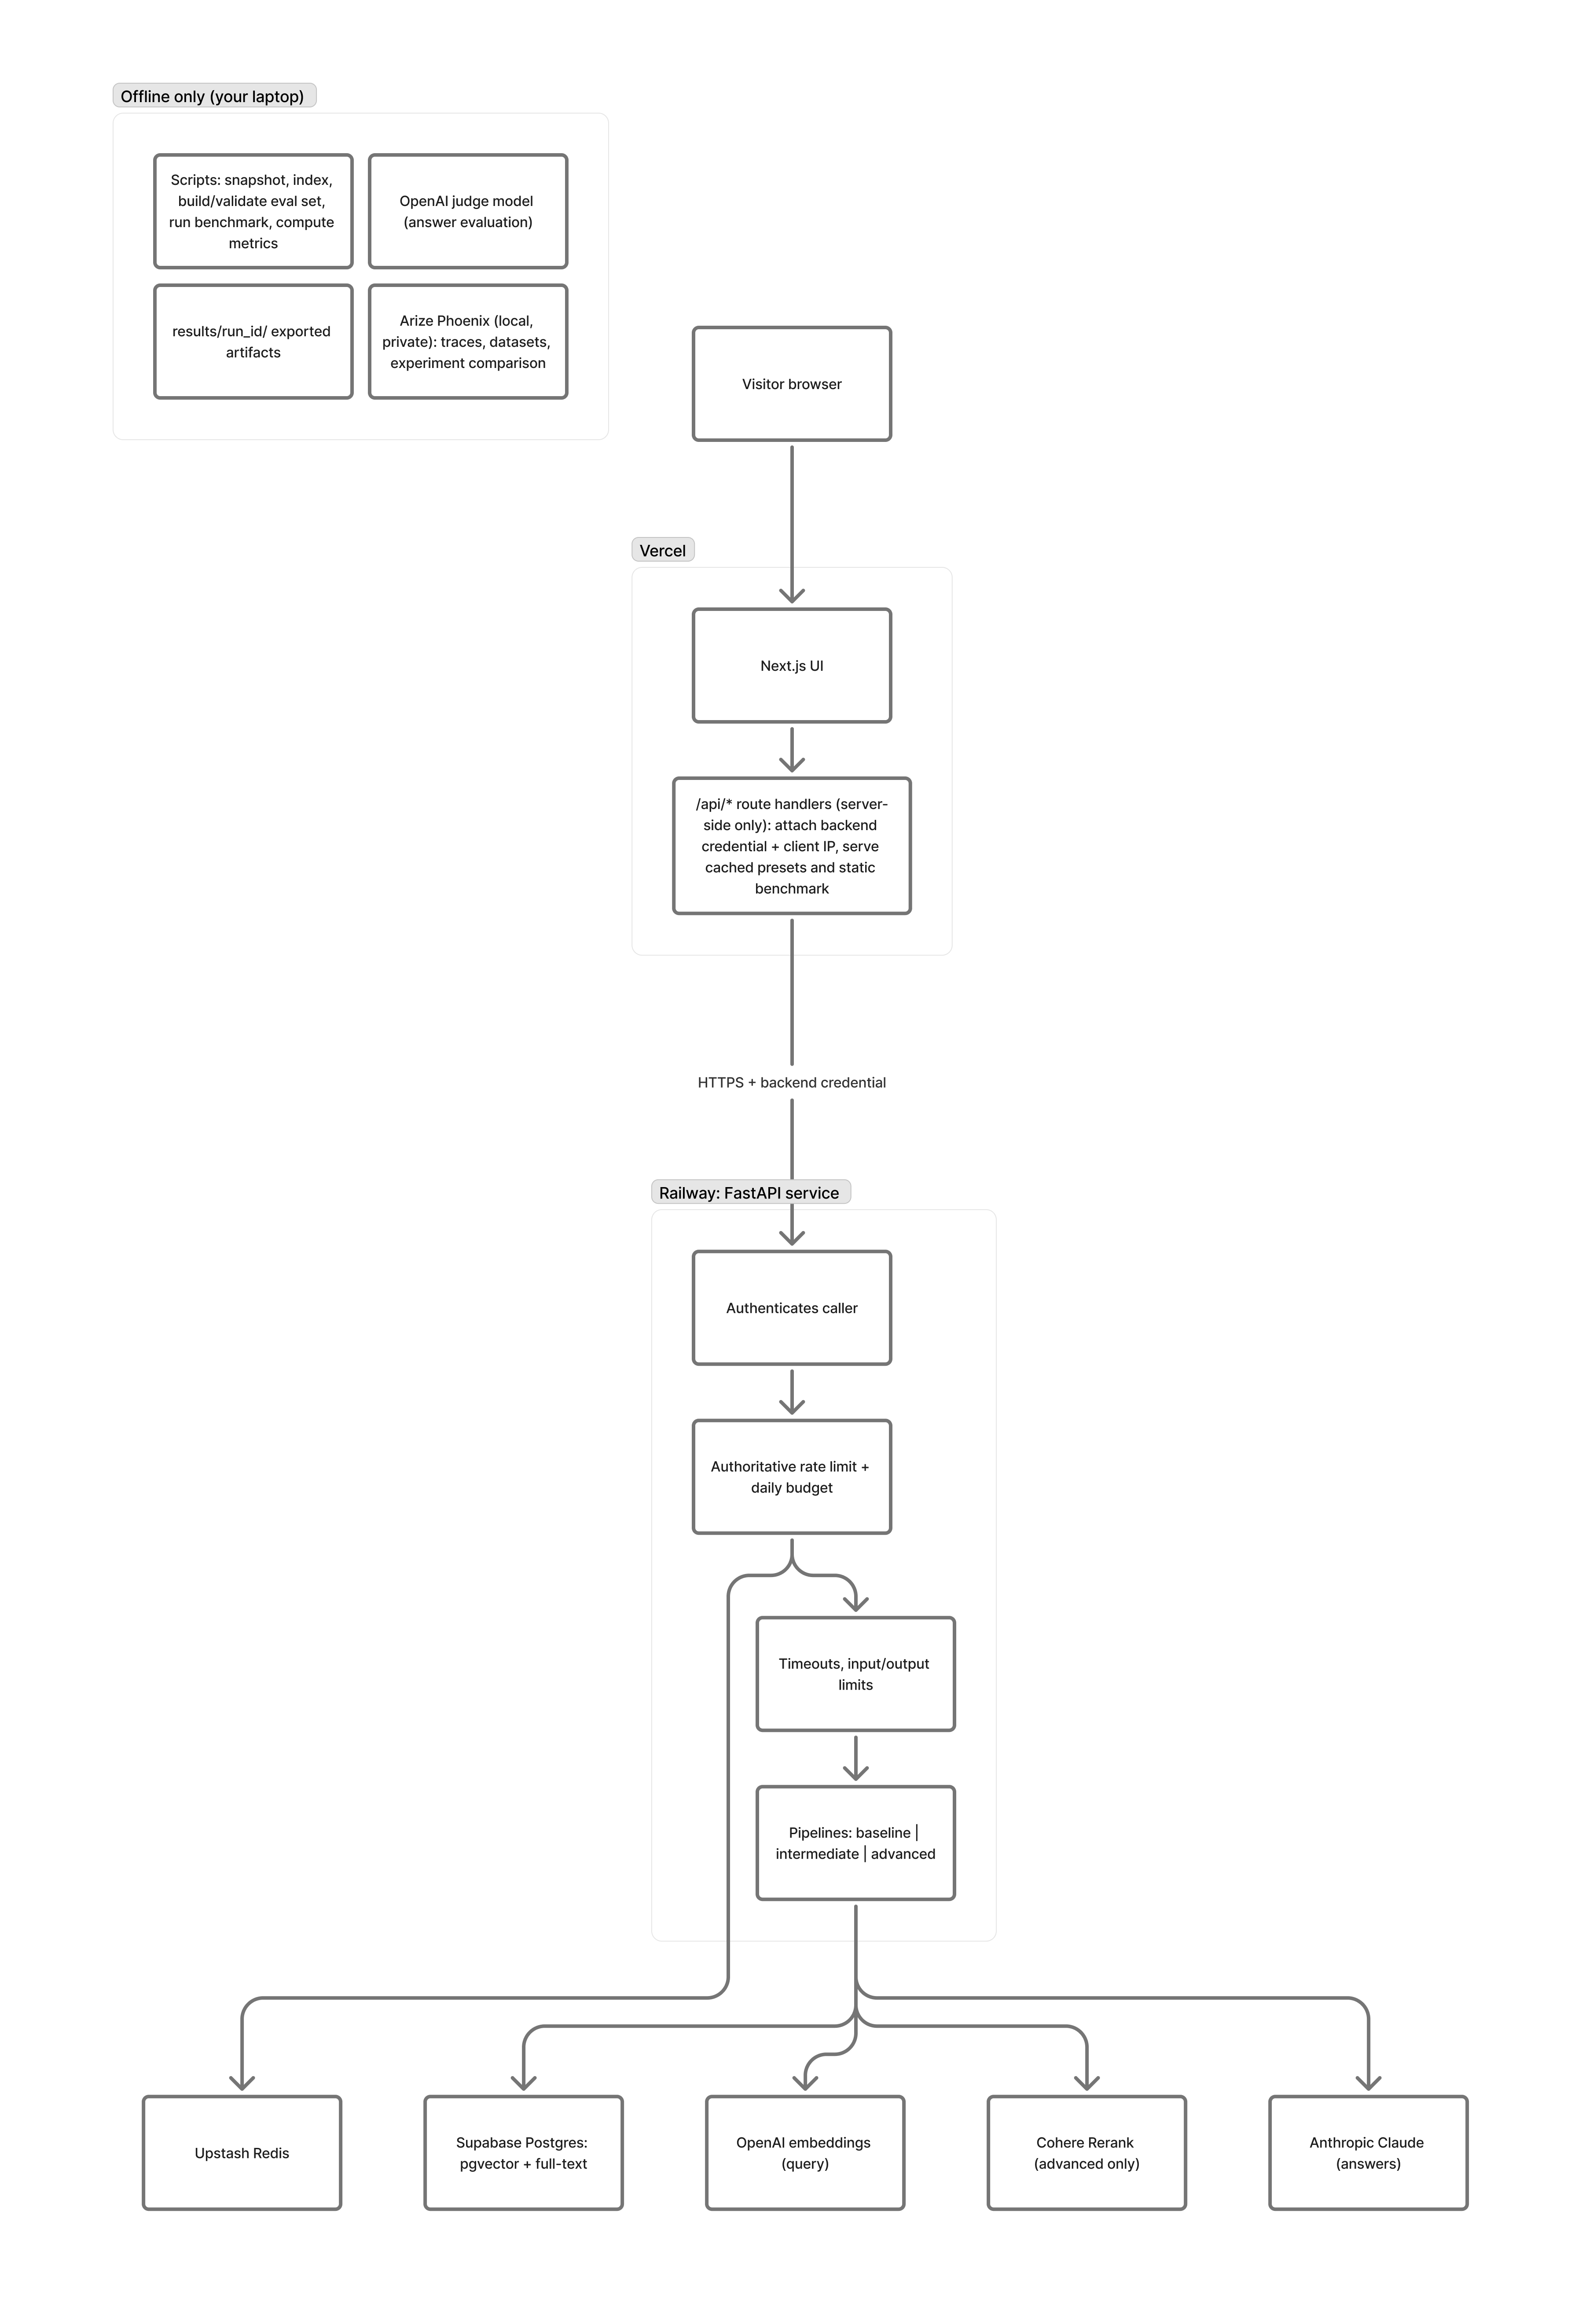
Three configurations
- Baseline: fixed-size chunks (about 400 tokens), dense vector search.
- Intermediate: structure-aware chunks split on headings, dense vector search.
- Advanced: the same chunks, dense plus keyword search fused with reciprocal rank fusion, then a cross-encoder reranker.
All three use the same documentation snapshot, questions, answer model, prompt and output limit, and pass the top 5 passages to the answer model.
How it is measured
Evidence is marked as character ranges in the source documents, so the comparison is fair even though the configurations cut the text differently. Retrieval is scored without any LLM. Answers are scored by a separate judge model, validated against human labels on a sample.
Source content: Kubernetes Documentation, © The Kubernetes Authors, licensed under CC BY 4.0. Normalized and chunked (modified). Full methodology, limitations and per-question results are in the GitHub repository.